



A website receives 1 million visitors every day. How many servers does it need?
Five servers? Ten? Twenty?
Surprisingly, there is no reliable answer based on visitor count alone.
A mostly static website serving cached pages through a CDN could handle very large traffic volumes with relatively little origin infrastructure. A dynamic application with authentication, database queries, search, personalization and API calls could require significantly more computing power for the same number of visitors.
The better question is:
How much traffic actually reaches the origin during peak periods, and how much of that workload can one server safely handle?
Once those two numbers are known, estimating server capacity becomes much more meaningful.
The Short Answer
One million daily visitors does not translate into a specific number of servers.
To estimate server requirements, you need to determine:
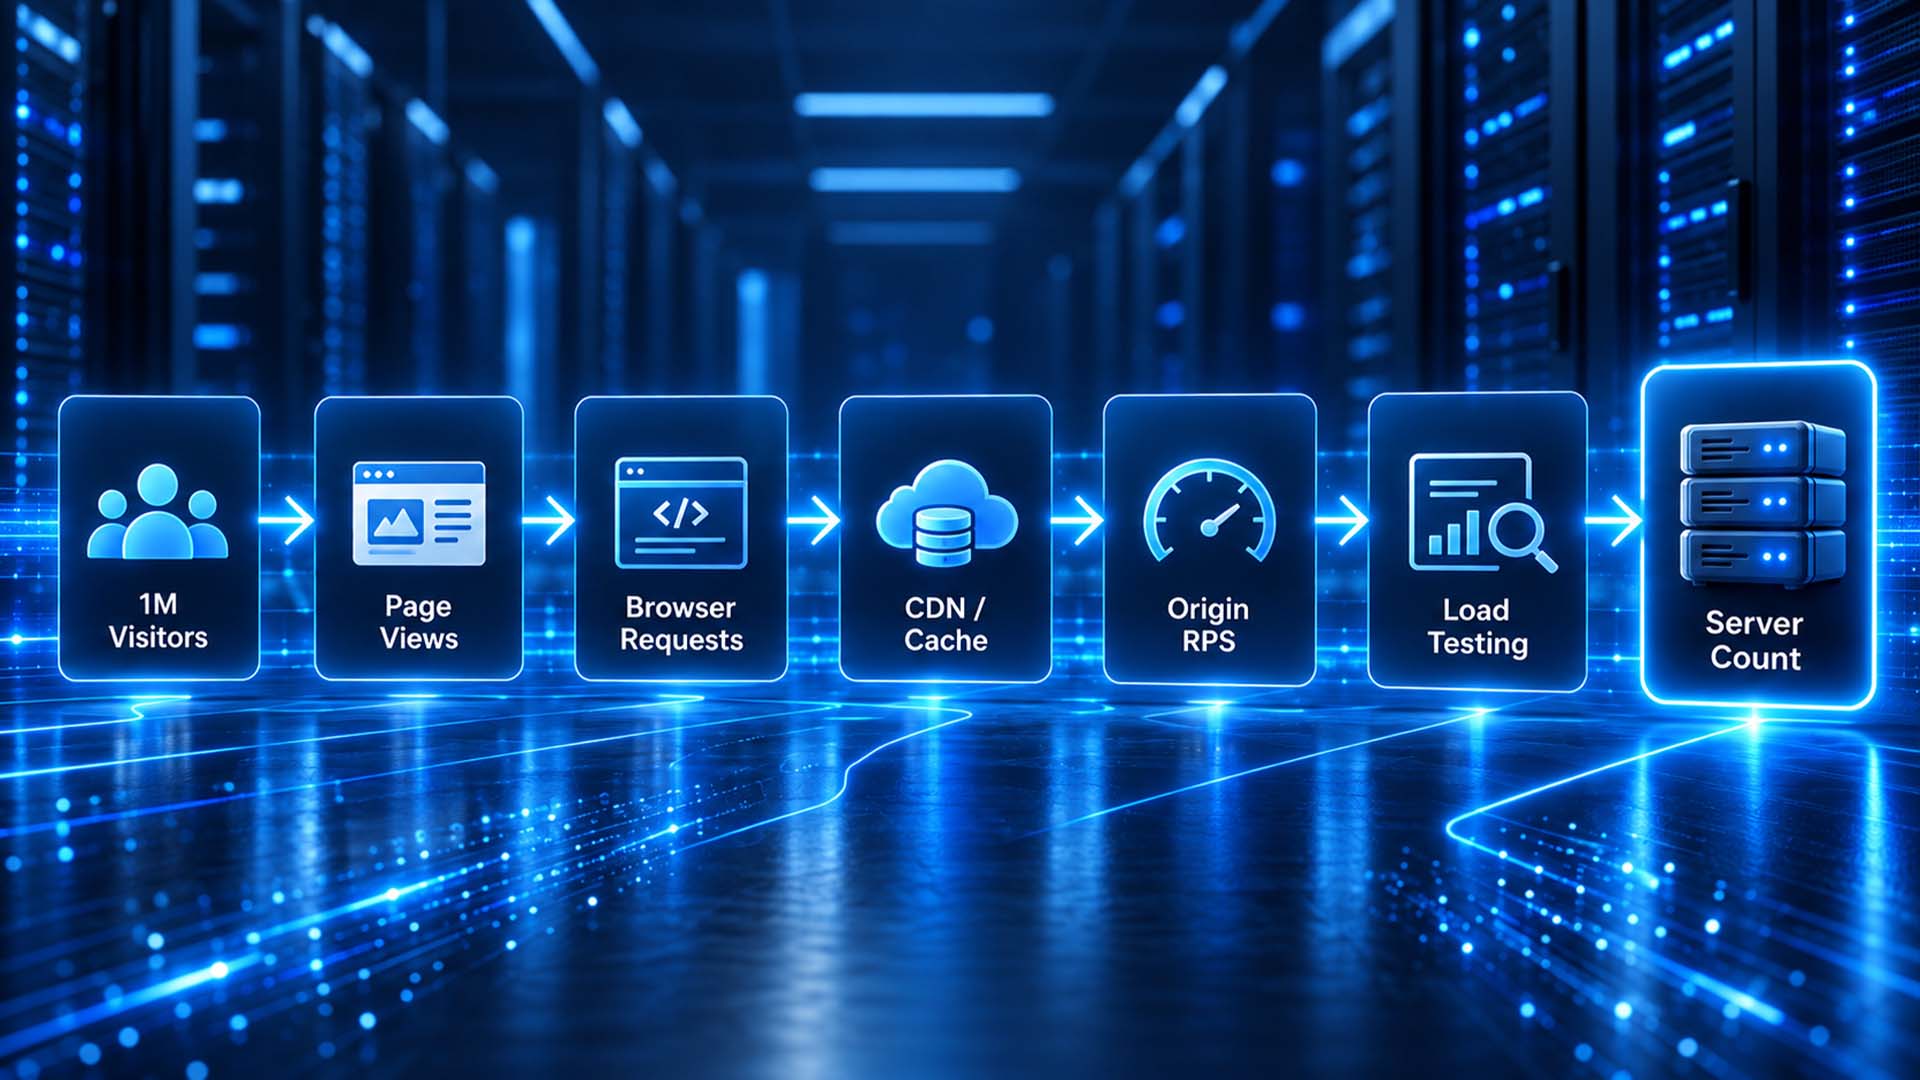
Visitors → Page Views → Browser Requests → CDN/Cache → Origin RPS → Load Testing → Server Count
In practice, the most important numbers are:
- Peak origin requests per second (RPS)
- Sustainable RPS per server
- Performance requirements
- Redundancy and safety margin
Let’s work through the process.
1. Visitors Are Not a Measure of Server Load
A visitor is a person or client session. A server processes requests.
Those are not the same thing.
One visitor might:
- open the homepage and leave;
- browse ten articles;
- perform several searches;
- log into an account;
- add products to a cart;
- send API requests;
- download files.
Two websites with one million visitors can therefore produce completely different workloads.
A useful starting point is:
Daily Visitors × Pages per Visit = Daily Page Views
But even page views do not tell us exactly how much work reaches the server.
2. One Page View Can Generate Dozens of HTTP Requests
Loading a modern webpage normally requires much more than downloading one HTML document.
The browser may request:
- HTML
- CSS
- JavaScript
- images
- fonts
- icons
- API responses
- analytics scripts
- advertising resources
- third-party services
According to the 2025 HTTP Archive Web Almanac, the median webpage generated around 77 requests on desktop and 72 on mobile. Median homepages generated roughly 80 and 75 requests respectively.
That does not mean every page view sends 70 or 80 requests to your application server.
And this distinction is extremely important.
3. Browser Requests Are Not the Same as Origin Requests
Suppose a visitor loads a page that generates 75 HTTP requests.
Some of those requests might be served by:
- the browser cache;
- a CDN;
- an image CDN;
- third-party analytics providers;
- external font services;
- advertising platforms;
- other APIs.
Your origin server may therefore see only a fraction of them.
This gives us two different concepts:
Browser Requests
Everything the browser requests while rendering the page.
Origin Requests
The requests that actually reach infrastructure you operate.
For server capacity planning, origin traffic matters far more than total browser requests.
This is also why introducing an effective CDN and caching strategy can dramatically change infrastructure requirements.
A request served from an edge cache may never reach your origin at all.
4. Start Measuring Origin RPS
RPS means Requests Per Second.
It measures how many requests your infrastructure processes each second.
Let’s use a simplified example.
Imagine our one-million-visitor website generates:
- 1,000,000 visits per day
- an average of 2 page views per visit
- an average of 5 origin requests per page view
These numbers are examples — not universal industry averages.
That produces:
1,000,000 × 2 × 5 = 10,000,000 origin requests per day
A day contains 86,400 seconds.
Therefore:
10,000,000 ÷ 86,400 ≈ 116 RPS
Our average load is approximately:
116 origin requests per second
It is tempting to size the infrastructure around this number.
That would be a mistake.
5. Design for Peak Traffic, Not Daily Average Traffic
Traffic rarely arrives evenly throughout the day.
Your site might receive relatively little traffic at 4:00 AM and several times the average load during the evening.
Marketing campaigns, viral posts, product launches and breaking news can create even sharper spikes.
Suppose 30% of our daily requests arrive within a two-hour peak window.
From our previous example:
10,000,000 × 30% = 3,000,000 requests
Two hours contain:
7,200 seconds
Therefore:
3,000,000 ÷ 7,200 ≈ 417 RPS
The average was only:
116 RPS
But during the busy period we need to handle approximately:
417 RPS
That difference is why infrastructure designed around daily averages can fail even when overall traffic numbers appear reasonable.
A useful formula
Peak RPS = Requests During Peak Window ÷ Peak Window in Seconds
Whenever possible, use actual production traffic data rather than assuming that 30%, 40% or another percentage of traffic arrives during a particular period.
6. Can You Calculate Server Capacity From CPU Cores?
A common shortcut looks like this:
Assume:
- one server has 8 CPU cores;
- each request takes 50 ms.
Since one second contains 1,000 milliseconds:
1,000 ÷ 50 = 20 requests per second
Then:
20 × 8 cores = 160 RPS
Therefore, the server supposedly handles 160 RPS.
The mathematics looks reasonable.
The model is not.
Modern web applications do not necessarily process one request per CPU core from beginning to end.
A request may spend much of its time waiting for:
- database queries;
- network I/O;
- caches;
- object storage;
- another internal service;
- external APIs;
- locks or queues.
Modern servers also process requests concurrently through combinations of processes, threads, event loops and asynchronous I/O.
Therefore:
Response time alone cannot tell you how many requests a server can handle.
An 8-core server does not automatically equal 160 RPS, 500 RPS or any other fixed throughput.
You have to measure it.
7. Load Testing Tells You What One Server Can Really Handle
This is where load testing becomes essential.
Instead of estimating server capacity from CPU specifications, send controlled traffic to the application and observe what happens as load increases.
Tools such as k6 allow engineers to model workloads and define performance thresholds such as response-time percentiles and acceptable error rates. Grafana’s k6 documentation, for example, demonstrates thresholds such as keeping 95% of requests below a target latency while limiting HTTP failures.
A useful load test might tell you:
One application server can sustainably process 200 RPS while keeping p95 latency below 250 ms and maintaining an acceptable error rate.
Now we finally have a meaningful capacity number.
Why p95 instead of average response time?
Suppose the average response time is 90 ms.
That sounds excellent.
But the average could hide users who routinely experience 800 ms, 2 seconds or worse.
A p95 latency of 250 ms means:
95% of measured requests completed within 250 ms.
For capacity planning, percentile latency usually provides more useful information than averages alone.
8. Calculate How Many Servers You Need
Now we have two important measurements.
Peak traffic:
417 RPS
Measured sustainable capacity of one server:
200 RPS
The simplest calculation is:
417 ÷ 200 = 2.085
Since we cannot operate 0.085 of a server, we round up:
3 servers
But running exactly enough capacity for expected traffic gives us little protection against unexpected events.
So we should add headroom.
9. Add a Safety Margin
Suppose we want 50% additional capacity.
Our peak requirement becomes:
417 × 1.5 = 625.5 RPS
If each server safely supports 200 RPS:
625.5 ÷ 200 = 3.13
Round up:
4 servers
A useful simplified formula is:
Server Count = Ceiling[(Peak RPS × Safety Factor) ÷ Sustainable RPS per Server]
For our example:
Ceiling[(417 × 1.5) ÷ 200] = 4 servers
But we are not finished yet.
10. Capacity and High Availability Are Different Problems
Four servers may provide enough performance capacity.
That does not automatically mean four servers provide the availability level you want.
Imagine all four are required to meet your planned capacity and one fails during peak traffic.
Your remaining capacity becomes:
3 × 200 = 600 RPS
Depending on the workload and performance target, that may no longer provide the desired safety margin.
A production architecture could therefore deploy an additional instance using an N+1 redundancy strategy.
In our simplified example:
- 4 servers provide planned workload capacity;
- 1 additional server provides failure tolerance.
That could lead to:
5 application servers
Notice how we arrived at five servers.
It was not because one million visitors automatically require five servers.
We reached the number by measuring:
- origin traffic;
- peak RPS;
- sustainable capacity per server;
- safety margin;
- redundancy requirements.
That’s a very different calculation.
11. Where Does the Load Balancer Fit?
Once multiple application servers are available, incoming traffic needs to be distributed between them.
That is one of the primary roles of a load balancer.
A simplified architecture might look like:
Visitors → CDN → Load Balancer → Application Servers → Cache / Database
A load balancer can:
- distribute requests among multiple servers;
- perform health checks;
- stop sending traffic to unhealthy instances;
- help applications scale horizontally;
- support more resilient deployments.
The AWS Well-Architected Framework recommends distributing traffic across multiple resources so workloads can improve utilization, elasticity and availability.
But a load balancer does not magically make an entire system highly available.
12. Five Web Servers Can Still Leave You With One Point of Failure
Imagine this architecture:
Load Balancer → 5 Web Servers → 1 Database
The web layer is redundant.
The database is not.
If that database fails, all five application servers might become useless.
The same issue can occur with:
- Redis or another cache;
- shared storage;
- queues;
- DNS;
- networking;
- authentication services;
- third-party APIs;
- the load-balancing layer itself.
True high availability therefore requires examining the entire request path, not simply adding more web servers.
13. A CDN Can Completely Change the Calculation
Consider two websites receiving identical traffic.
Website A
Every request reaches the origin.
Its application servers repeatedly send:
- images;
- CSS;
- JavaScript;
- static HTML;
- other cacheable files.
Website B
A CDN serves most static and cacheable content from edge locations.
Only dynamic or uncached requests reach the origin.
Both sites may report:
1 million visitors per day
But their origin workloads could be dramatically different.
That’s why the useful metric is not:
How much traffic does the website receive?
It is:
How much peak traffic reaches the origin?
14. Static Websites and Dynamic Applications Are Very Different
Visitor numbers become even less meaningful when we compare different types of websites.
Static or heavily cached website
Examples include:
- documentation;
- blogs;
- news archives;
- static landing pages.
A large percentage of traffic may be served directly from a CDN.
The origin may handle surprisingly little traffic.
Dynamic website
Examples include:
- WooCommerce stores;
- membership websites;
- dashboards;
- SaaS applications.
More requests may require:
- PHP or application execution;
- authentication;
- session management;
- database queries;
- personalized responses.
Computationally expensive application
Applications involving:
- AI inference;
- video processing;
- large searches;
- complex database queries;
- real-time data processing
may consume far more resources per request.
The same 417 RPS can therefore represent completely different infrastructure requirements.
15. Requests Per Second Are Not Enough Either
RPS is far more useful than visitor count, but it is still not the whole story.
Imagine two APIs.
API A
Each request:
- reads a cached value;
- uses very little CPU;
- completes in 10 ms.
API B
Each request:
- performs multiple database joins;
- calls external APIs;
- transforms large datasets;
- takes 800 ms.
Both may receive:
100 RPS
Their infrastructure requirements can be radically different.
Server capacity planning should therefore consider:
- RPS;
- CPU utilization;
- memory;
- disk and network I/O;
- database capacity;
- cache hit ratio;
- latency;
- error rates;
- concurrency;
- application behavior.
A Better Way to Size Website Infrastructure
Instead of starting with:
We have one million visitors, so how many servers should we buy?
Use this process:
1M Visitors
↓
Page Views
↓
Browser Requests
↓
CDN & Cache
↓
Peak Origin RPS
↓
Load Test Each Application Instance
↓
Add Headroom and Redundancy
↓
Determine Server Count
That is the core principle behind realistic server capacity planning.
Example: From 1 Million Visitors to Server Count
Let’s combine our hypothetical numbers.
| Metric | Example |
|---|---|
| Daily visitors | 1,000,000 |
| Page views per visitor | 2 |
| Origin requests per page | 5 |
| Daily origin requests | 10,000,000 |
| Average RPS | ~116 |
| Traffic during two-hour peak | 30% |
| Peak RPS | ~417 |
| Tested capacity per server | 200 RPS |
| Headroom | 50% |
| Required capacity | ~626 RPS |
| Servers needed for capacity | 4 |
| Optional N+1 redundancy | +1 |
| Example deployment | 5 servers |
Again, these are illustrative numbers.
The important part is the method, not the final number.
So, How Many Servers Does 1 Million Daily Visitors Really Need?
There is no universal number.
A million daily visitors might require:
- a small origin server behind a highly effective CDN;
- several application servers behind a load balancer;
- dozens of instances;
- or an automatically scaling architecture where the server count changes throughout the day.
The number of visitors alone simply does not contain enough information.
For practical capacity planning, determine:
Peak Origin RPS
and then measure:
Sustainable RPS per Application Instance
After that, account for headroom, failures and growth.
That gives you a server count based on how the application actually behaves rather than an arbitrary visitors-to-servers formula.
Final Takeaway
The question:
“How many servers do I need for one million visitors?”
starts in the wrong place.
Visitors do not directly consume CPU cores. Requests and workloads do.
A much better capacity-planning model is:
Traffic → Peak Origin RPS → Load Testing → Headroom → Redundancy → Server Count
Once you understand those numbers, infrastructure planning stops being guesswork.
And that distinction is often the difference between an architecture that merely looks powerful and one that can actually survive real-world traffic.